Visão geral de Duplicate Content Finder: Free Thin Audit
Finds same and near-same text across pages
Flags repeated titles, descriptions, headings
Lists thin pages and thin product pages
Which page to keep hint, CSV download
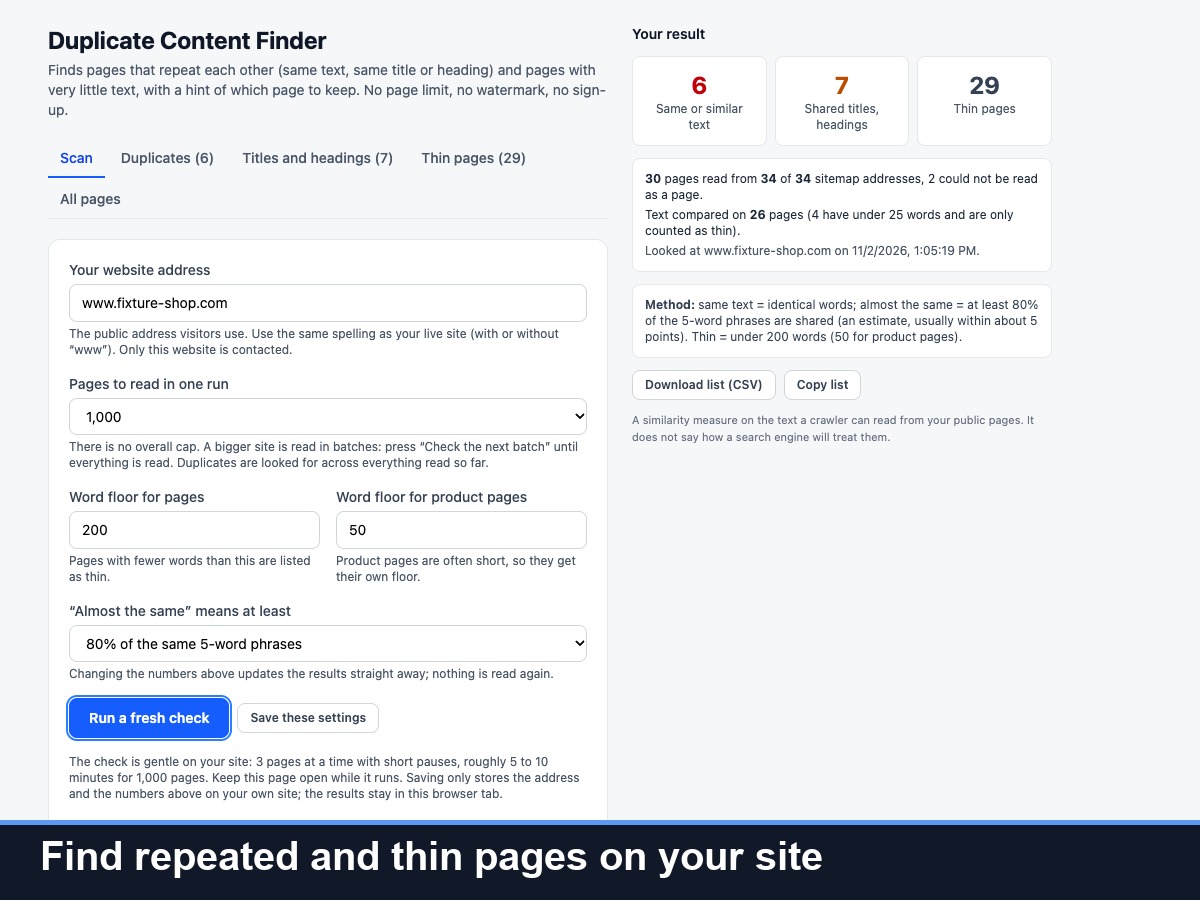
Duplicate Content Finder reads your public pages the way a crawler does and shows where your own pages repeat each other.
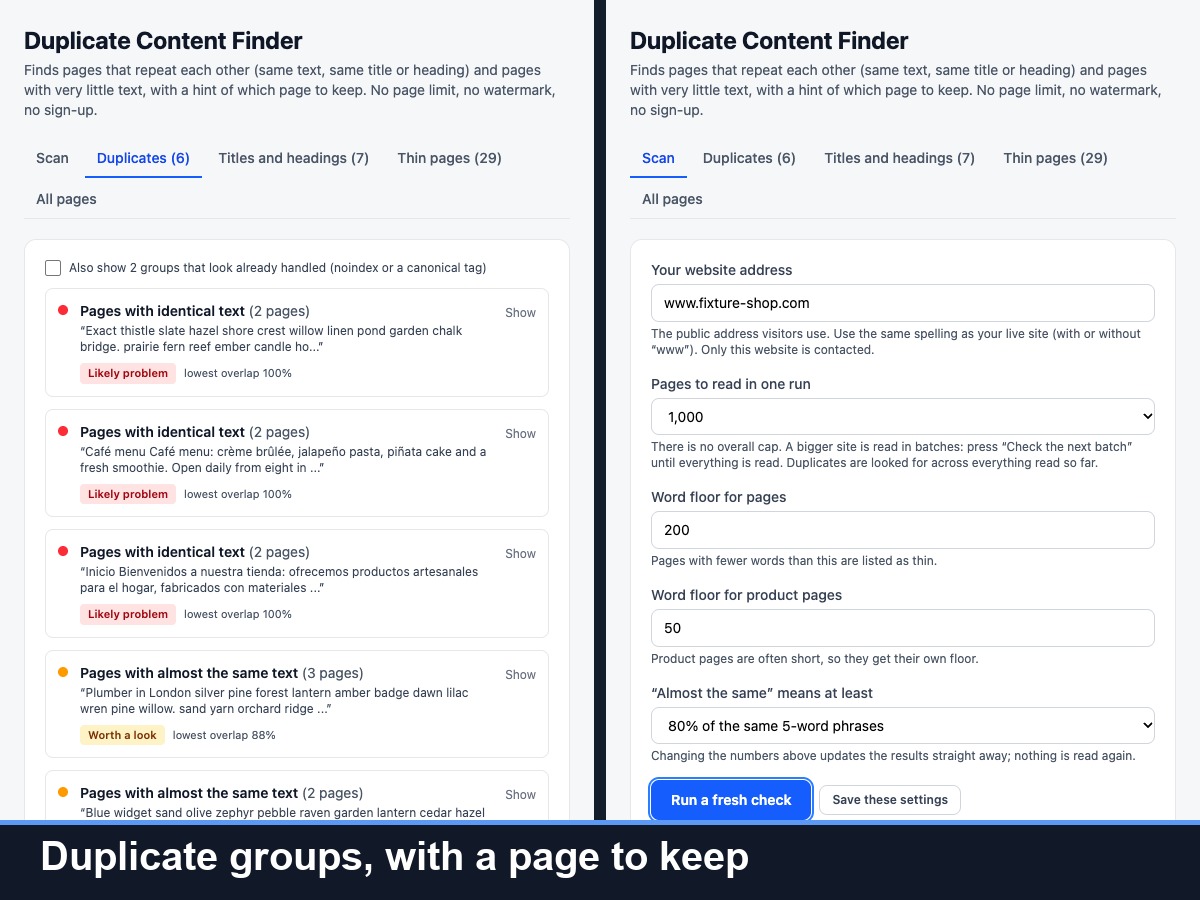
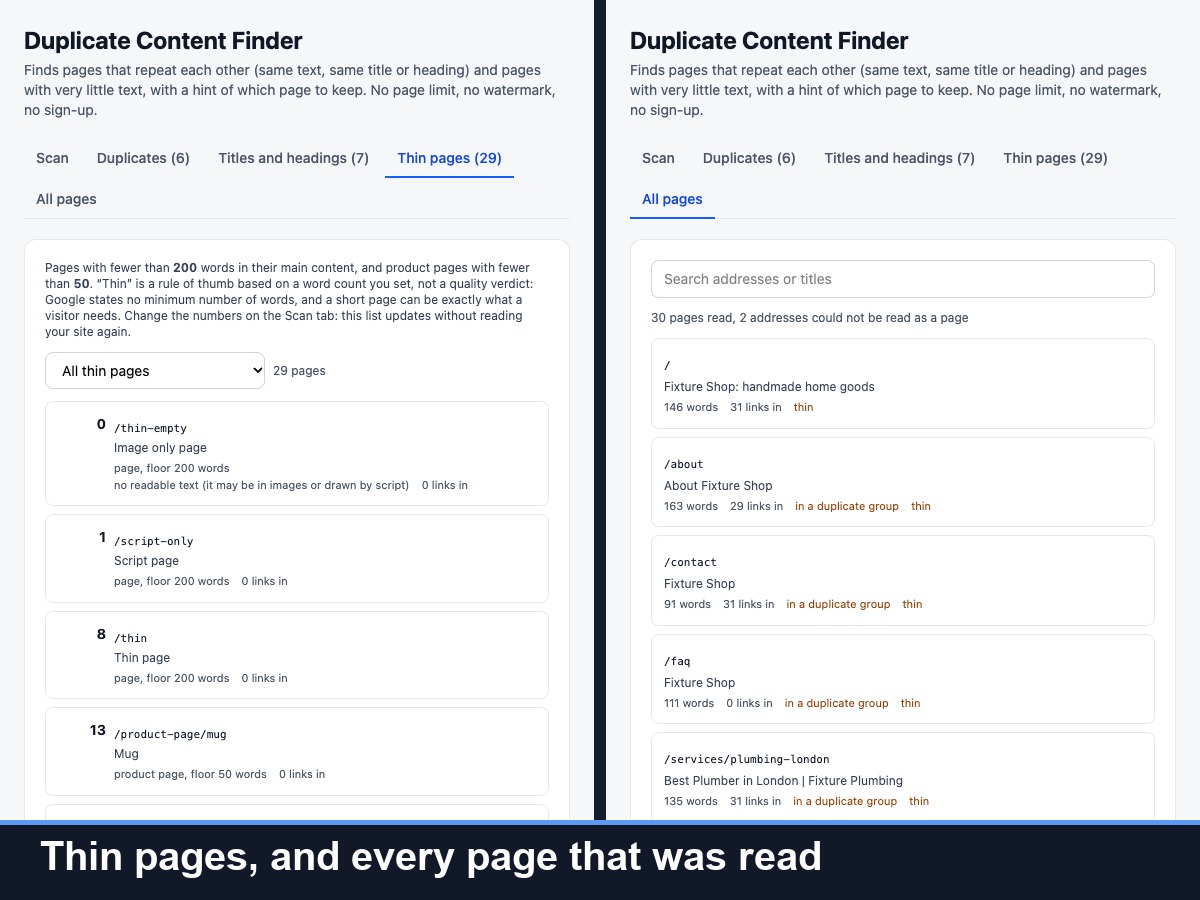
It reads every page in your sitemap, in gentle batches, and compares the main text of each page (menus, headers and footers are left out). It groups pages with the same text, pages with almost the same text (you choose the percentage), and pages that share a title, meta description or main heading. For each group it suggests which page to keep, from address length, canonical tags, links in and text length, and says why. It also lists thin pages and thin product pages (you set the word floors) and exports a CSV.
How it measures: almost the same means the share of 5-word phrases two pages have in common, estimated from a small fingerprint (usually within about 5 points). It is a similarity measure, not a verdict.
No page caps, no watermark, no sign-up. The last result stays in your browser tab only.
What it cannot do: say how Google treats your pages, promise rankings, run JavaScript (text drawn by script or in images is not counted), compare you with other sites or change your site. A firewall that blocks bots can make pages look unreadable.